Codex vs Cursor — Cursor vs Codex: 2 side-by-side tests
2 posts from X ran OpenAI Codex and Cursor on the same task, between Aug 8, 2025 and Oct 19, 2026. Models: Claude Opus 5.5, Muse Wonder 1.0, GPT-6 Astra, Claude Opus 4.1, GPT-5. All harness comparisons.
- 1 post states a time for both, split evenly.
- 1 post states a token count for both: OpenAI Codex used fewer tokens in it, by ~1.8×.
- 1 of 2 keeps the model fixed (GPT-5); in the rest each side ran its own model, so harness and model effects are mixed.
From 2 posts; costs and times as stated by each author, not a controlled benchmark.
Posts
2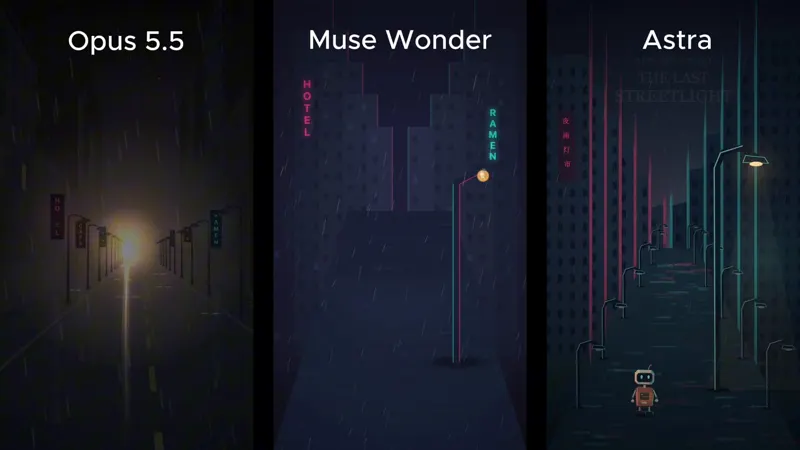


Codex vs Cursor, test by test
| Test | Codex: model | Cursor: model | Time (Codex / Cursor) | Tokens (Codex / Cursor) | Author’s pick |
|---|---|---|---|---|---|
| “The Last Streetlight” short in three agents@SKatalystAI | GPT-6 Astra | Muse Wonder 1.0 | 60 s / 60 s | — | — |
| Next.js customer feedback app@iannuttall | GPT-5 | GPT-5 | — | 102,000 / 188,000 | — |
Numbers are as each post states them; “—” means the post gives none. Tests and models differ from row to row.
Codex vs Cursor pricing: plans
From each vendor’s official pricing page (checked 2026-10-19); prices exclude tax and can change. Usage limits differ by plan and model.
API list prices of the models in these tests
| Model | Used with | Input $/1M tokens | Output $/1M tokens |
|---|---|---|---|
| GPT-6 Astra | Codex | $10 | $50 |
| GPT-5 | Codex, Cursor | ||
| Muse Wonder 1.0 | Cursor | $4 | $20 |
Official API list prices where verified; a blank cell has no verified official price in the archive (older or retired models).
What each test showed
Unless a test says both sides ran the same model, each side ran its own model — not a controlled comparison of the harnesses alone.
“The Last Streetlight” short in three agents — GPT-6 Astra in Codex vs Muse Wonder 1.0 in Cursor
Claude Code with Claude Opus 5.5, Cursor with Muse Wonder and Codex with GPT-6 Astra each code a Pixar-style short about a robot, a cat and a rainy city, with no assets or libraries, then run three rounds of self-critique. The post also includes Claude Code.
- Claude Code with Claude Opus 5.5: time 77 s — Left; self-score 4.5–6/10.
- Cursor with Muse Wonder 1.0: time 60 s — Middle; self-score 6.2/10.
- OpenAI Codex with GPT-6 Astra: time 60 s — Right; self-score 6.8/10.
As stated: 85 KB, 77 sec, 4.5–6/10; 32 KB, 60 sec, 6.2/10; 25 KB, 60 sec, 6.8/10. The scores are each system’s own self-critique, not an independent benchmark.
Posted Oct 19, 2026 by Sinda | SKatalyst AI (@SKatalystAI). Original post on X · Video and details
Next.js customer feedback app — GPT-5 in Codex vs GPT-5 in Cursor
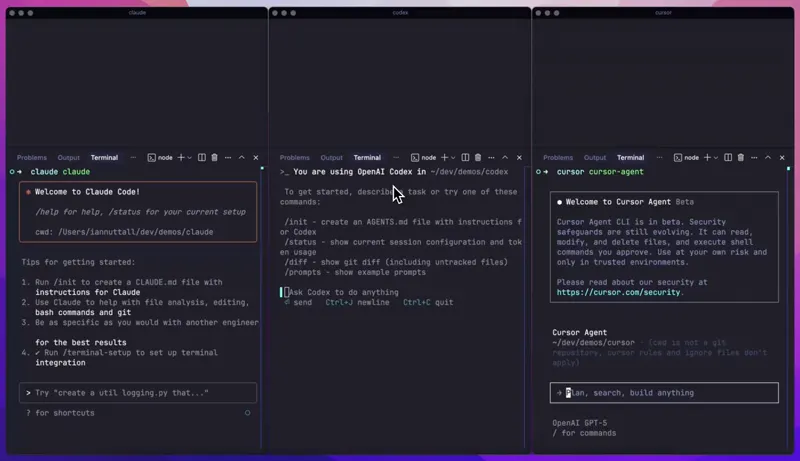
Claude Code with Claude Opus 4.1, Codex with GPT-5 and Cursor's CLI agent with GPT-5 get the same prompt: a Next.js app with Tailwind 4 and shadcn that collects customer feedback and shows it in a widget, with 30 minutes each. Both sides ran GPT-5, so this one isolates the harness. The post also includes Claude Code.
- Claude Code with Claude Opus 4.1: 33,000 tokens — Working app with no errors after one correction; basic design; fastest. Author’s pick.
- OpenAI Codex with GPT-5: 102,000 tokens — No working app after 30 minutes (stuck on Tailwind 4 setup, “failed to compile”).
- Cursor Agent (CLI) with GPT-5: 188,000 tokens — Slowest; working app after one or two small fixes; minimal design.
Each harness got the same prompt and 30 minutes. Token counts are as the post states them.
Verdict from @iannuttall: “Opus is still the more capable model out of the box and Claude Code is the more complete CLI product”
Posted Aug 8, 2025 by Ian Nuttall (@iannuttall). Original post on X · Video and details
Codex vs Cursor (Cursor vs Codex): FAQ
Is Codex better than Cursor?
None of the 2 posts names a winner between the two.
Which is faster, Codex or Cursor?
Neither, going by the posts' own numbers: the one post that gives a time for each side shows a tie. Times are as each author states them; models and settings differ.
Which is cheaper, Codex or Cursor?
Codex plans (official pricing page, checked 2026-10-19): Free $0/month, Go $8/month, Plus $20/month, Pro From $100/month, Business $25/user/month, API key API pricing.
Did any test run the same model in Codex and Cursor?
Yes, in 1 of the 2: Next.js customer feedback app (@iannuttall) ran GPT-5 on both sides. The others pair each harness with a different model.
Which models were used with Codex and Cursor?
With Codex: GPT-6 Astra, GPT-5. With Cursor: Muse Wonder 1.0, GPT-5.