AI Coding
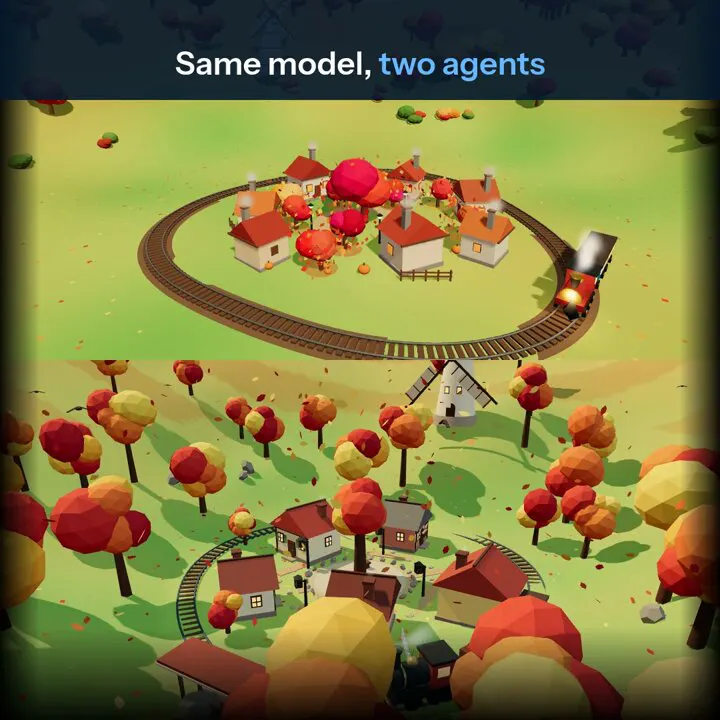
Voxel world on one Mac Studio, local Flash models — Qwen 3.8 Flash Next vs DeepSeek V4.1 Flash 1017

Scoreboard2
- Qwen 3.8 Flash NextAlibaba (Qwen)
- Time
- 58.1 min
- Tokens
- 225.9K
- Top; oQ4e quant with MTP, run in Qwen Code 0.25.2; 58.1 agent minutes, ended by the tool-call cap
- DeepSeek V4.1 Flash 1017DeepSeekDeepSeek HarnessAuthor’s pick
- Time
- 1 h 06 min
- Tokens
- 168.2K
- Bottom; LSQ3-G128 quant, DeepSeek Harness 0.2.1-rc.2; 65.7 agent minutes
Prompt
Voxel world on one Mac Studio, local Flash modelsThe post doesn’t quote the prompt wording.
The author likes the DeepSeek world much better, even though Qwen decodes about 2.4 times faster.
@niklaslenz_ai’s view (paraphrased)
Qwen 3.8 Flash Next (top) and DeepSeek V4.1 Flash 1017 (bottom) run locally on one 256 GB Mac Studio with the same voxel-world prompt, each in its maker’s own coding agent, thinking on, one try.
The post, itemised
- Kind
- Side-by-side
- Task
- Voxel world on one Mac Studio, local Flash models
- Category
- 3D & Shaders
- Mode
- Agentic
- Posted
- Video length
- 38 s
- Likes
- 4
- Views
- 407
- Bookmarks
- 2
- Sponsored
- No
NotesBoth models ran quantized on oMLX on the author’s own machine, so results reflect these local quants, not the hosted APIs.
Cost & time, as stated in the postAs stated: Qwen 3.8 Flash Next 58.1 agent minutes, 225,892 tokens, browser check 8.5/10; DeepSeek V4.1 Flash 1017 65.7 minutes, 168,228 tokens, 8/10.
Related
Posted by @niklaslenz_ai on X. aivs.tv claims no ownership: it hosts a copy for fast playback and links to the post on X. Request removal