Same model over timeSingle-run anecdoteAI Coding
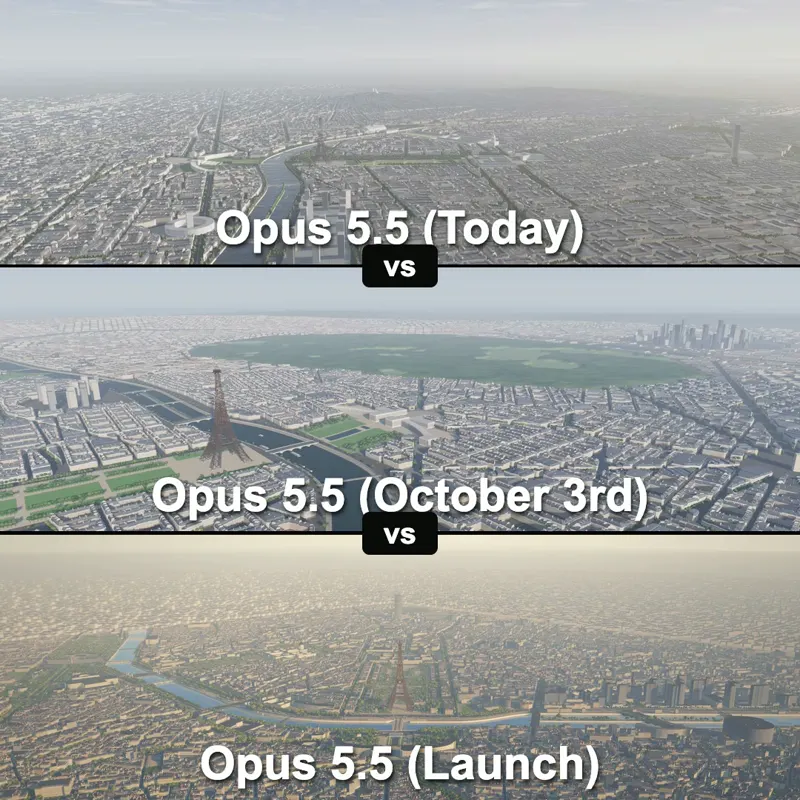
Eiffel Tower benchmark rerun — Claude Opus 5.5 (at launch) vs Claude Opus 5.5 (Oct 3)

Scoreboard2
- Claude Opus 5.5Anthropic
- Written as “Opus 5.5”
- Bottom, labelled “Opus 5.5 (Launch)”
- Claude Opus 5.5Anthropic
- Written as “Opus 5.5”
- Top, labelled “Opus 5.5 (Today)”; “Today” in the post, dated by the post (UTC)
Prompt
Eiffel Tower benchmark rerunThe post doesn’t quote the prompt wording.
They prefer the launch run: the tower may have slightly more detail now, but the buildings, trees and river look worse, and one run doesn't prove a nerf.
@EnvolDev’s view (paraphrased)
Claude Opus 5.5 reruns the author's Eiffel Tower benchmark with the same prompt it got at launch. The author prefers the launch result: the tower may be slightly more detailed now, but the city around it looks worse to them.
Same model, same prompt, run on different dates: one sample each, not a controlled test. Model outputs vary from run to run, so the poster’s claim is not verified here. All same-model-over-time posts.
The post, itemised
- Kind
- Side-by-side
- Task
- Eiffel Tower benchmark rerun
- Category
- 3D & Shaders
- Mode
- Not stated
- Posted
- Video length
- 20 s
- Likes
- 1,046
- Views
- 264,065
- Bookmarks
- 252
- Sponsored
- No
Related
Posted by @EnvolDev on X. aivs.tv claims no ownership: it hosts a copy for fast playback and links to the post on X. Request removal