Same model over timeSingle-run anecdoteAI Coding
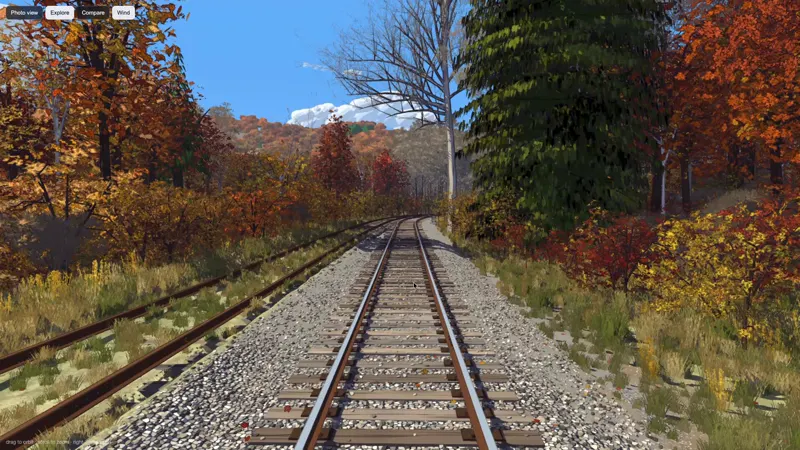
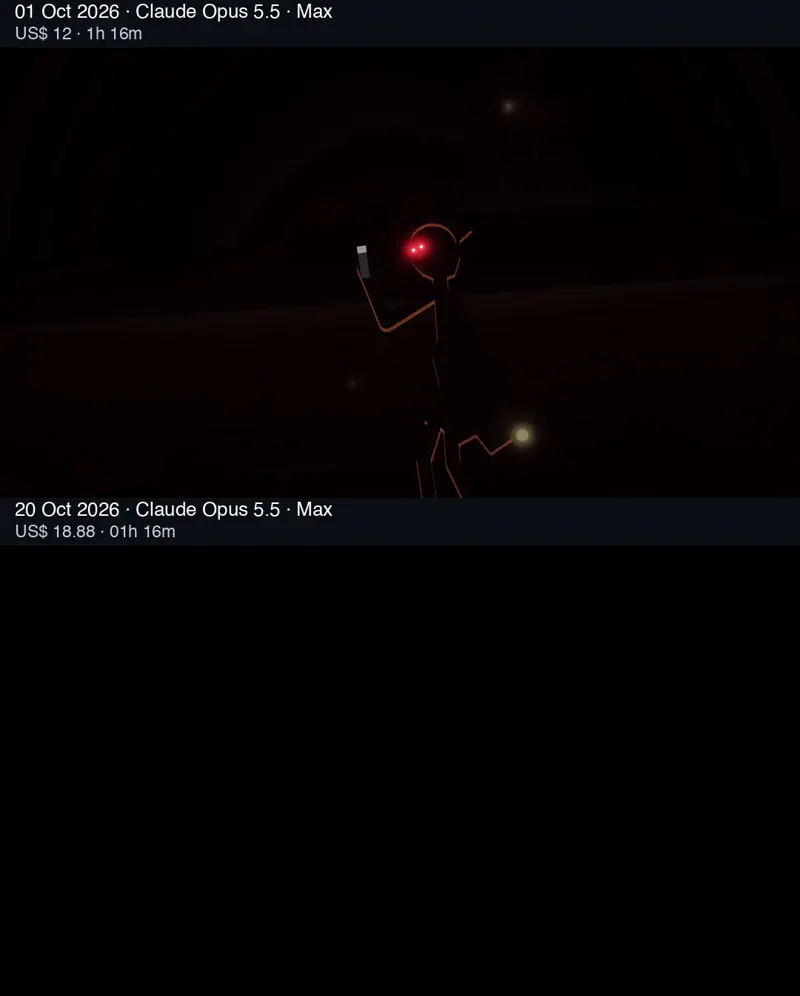
Night train benchmark rerun — Claude Opus 5.5 (at launch) vs Claude Opus 5.5 (Oct 4)

Scoreboard2
- Claude Opus 5.5Anthropic
- Written as “Opus 5.5”
- Bottom, labelled “Opus 5.5 (Launch)”
- Claude Opus 5.5Anthropic
- Written as “Opus 5.5”
- Top, labelled “Opus 5.5 (Today)”; “Today” in the post, dated by the post (UTC)
Prompt
Night train benchmark rerunThe post doesn’t quote the prompt wording.
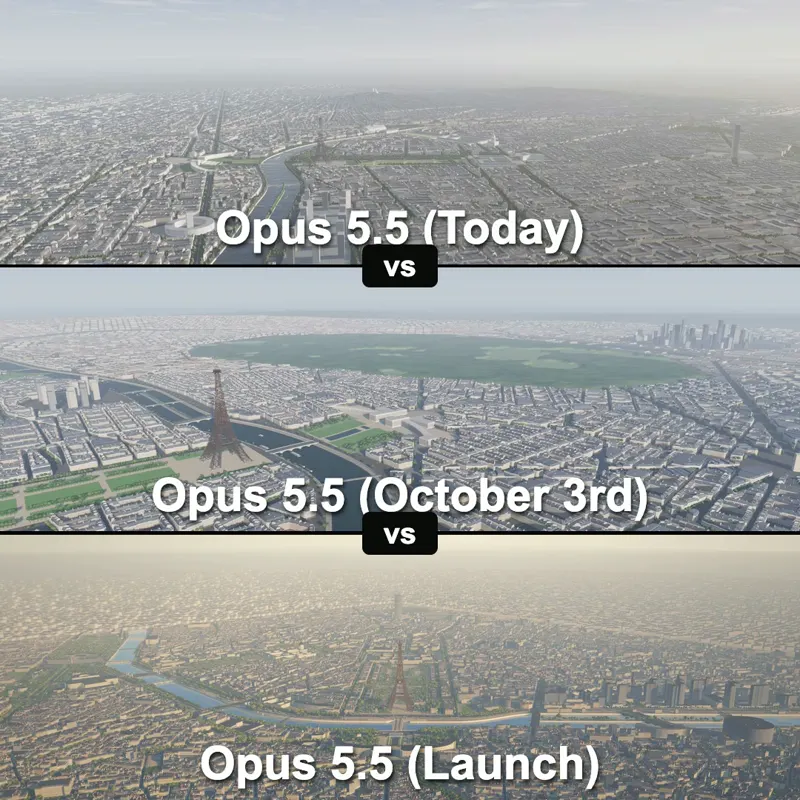
They say today's Opus 5.5 night train is worse than the launch run: small details up, overall scene down, as in their Eiffel Tower rerun.
@EnvolDev’s view (paraphrased)
Claude Opus 5.5 reruns the author's night train benchmark with the same prompt it got at launch. The author says this one is worse: small details are up but the overall scene is down, as in their Eiffel Tower rerun.
Same model, same prompt, run on different dates: one sample each, not a controlled test. Model outputs vary from run to run, so the poster’s claim is not verified here. All same-model-over-time posts.
The post, itemised
- Kind
- Side-by-side
- Task
- Night train benchmark rerun
- Category
- 3D & Shaders
- Mode
- Not stated
- Posted
- Video length
- 25 s
- Likes
- 330
- Views
- 70,581
- Bookmarks
- 78
- Sponsored
- No
Related
Posted by @EnvolDev on X. aivs.tv claims no ownership: it hosts a copy for fast playback and links to the post on X. Request removal