FawnBench (3D deer)
aka Fawn Bench · deer test
Make a deer (FawnBench).
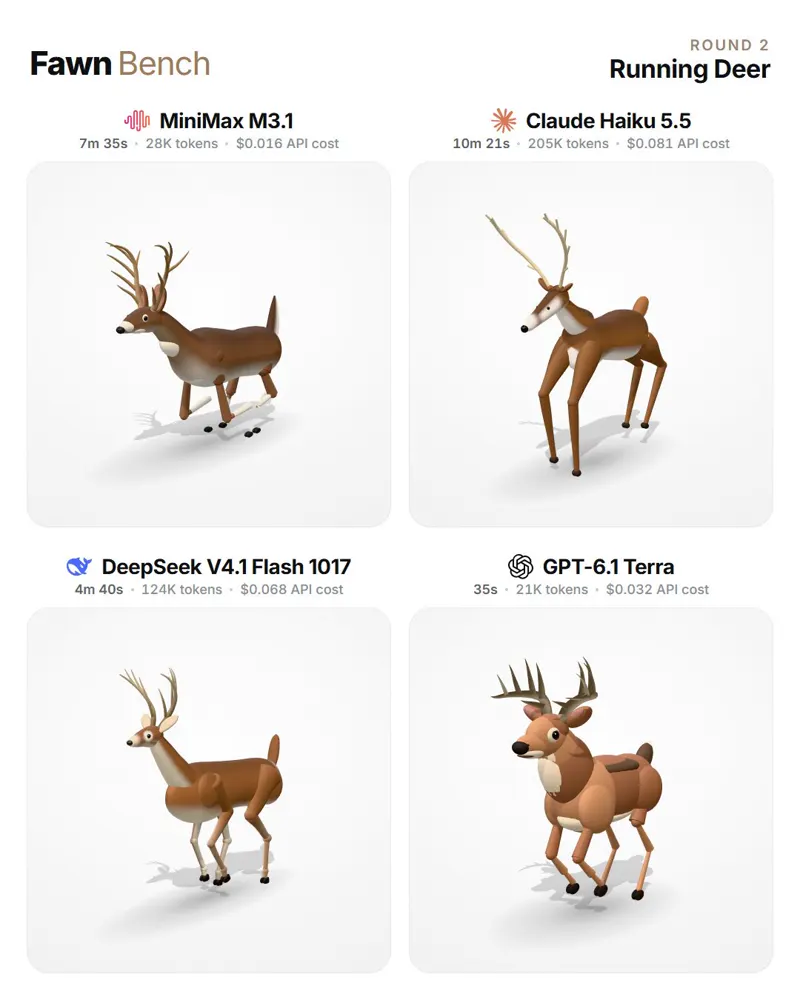
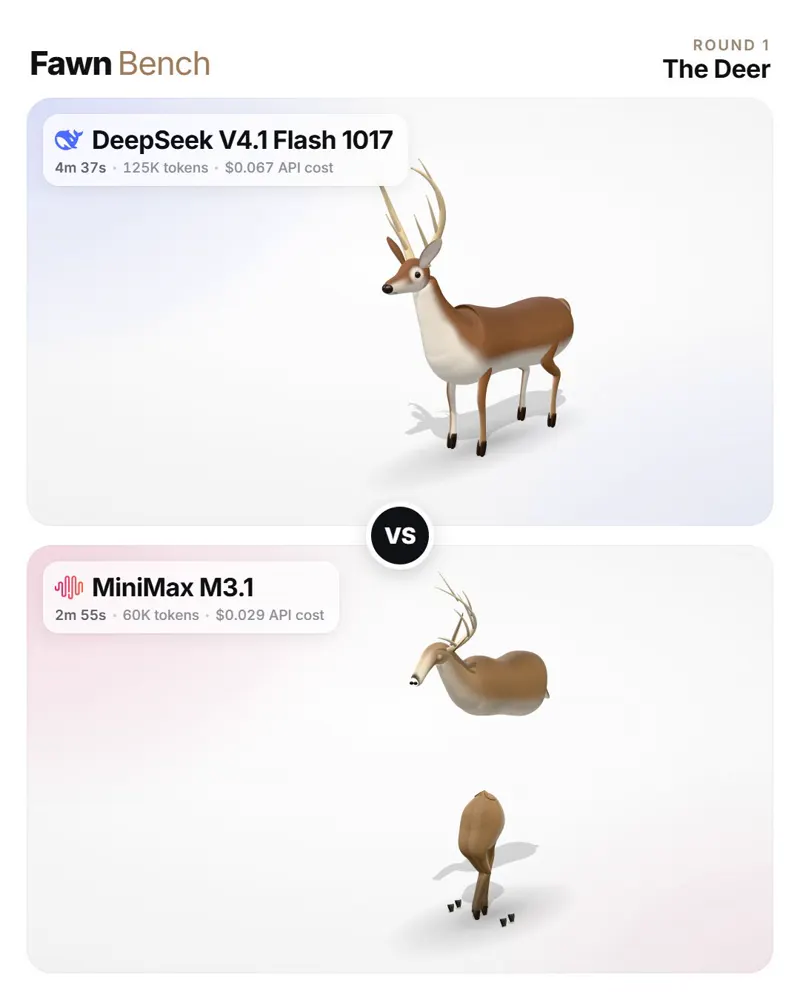
- DeepSeek V4.1 Flash 1017$0.067–$0.068 · 4.7 min–5 min
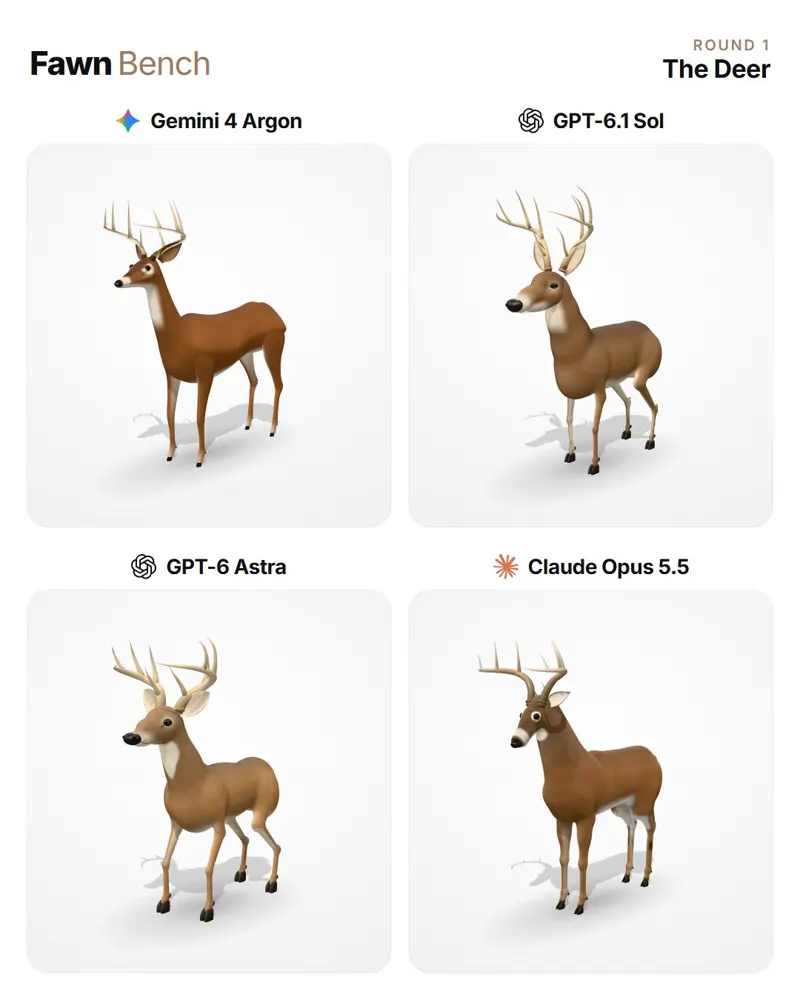
- Claude Opus 5.5$2.09 · 16.9 min
- Gemini 4 Argon$0.67 · 12.7 min
- GPT-6 Astra$0.94 · 6.5 min
- MiniMax M3.1 Flash$0.016–$0.029 · 3 min–7.6 min
- Claude Haiku 5.5$0.081 · 10.3 min
- GPT-6.1 Sol
- GPT-6.1 Terra$0.032 · 35 s
Not a controlled comparison: prompts, tools and time differ.
By model
4 posts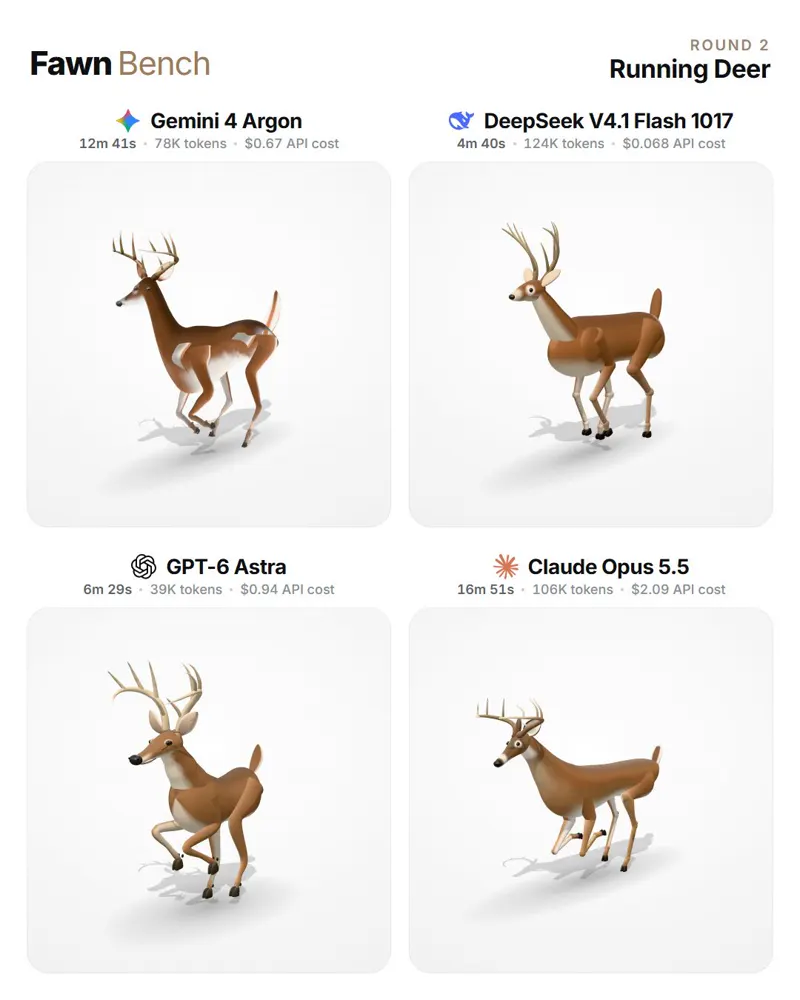

About this test
The FawnBench (3D deer) test, run by 8 models across 4 posts on X. Watch each result, then compare what the posts report below.
FawnBench is @fawnunwrap’s own test: each model is asked to make a deer, and in round 2 (the motion test) a running deer. Results are shown side by side in one video grid; the round 2 labels show each model’s time, tokens and API cost. The full prompt is not published, and every post here is from the benchmark’s creator.
Origin: @fawnunwrap’s “FAWNBENCH” (October 19, 2026): “This is my benchmark… (its js making a deer.)”
No fixed wording; posts use variations on the same idea.
Other wordings
Round 2, Running Deer: the deer runs (motion test).
FawnBench: questions and answers
Which AI model wins FawnBench?
None has been named. In all 3 FawnBench posts here, the creator @fawnunwrap leaves the verdict to readers: “who do you guys think did best?” for the first run and “I really only like one of them… Who won?” for the round 2 motion test. In the DeepSeek V4.1 Flash 1017 vs MiniMax M3.1 Flash run, the author only says DeepSeek “didn’t do bad for the price”.
What does a FawnBench run cost?
Only as stated by the author. In the round 2 video labels: Gemini 4 Argon 12m 41s, 78K tokens, $0.67; DeepSeek V4.1 Flash 1017 4m 40s, 124K tokens, $0.068; GPT-6 Astra 6m 29s, 39K tokens, $0.94; Claude Opus 5.5 16m 51s, 106K tokens, $2.09 (API cost). In the two-model run, DeepSeek V4.1 Flash 1017 cost $0.067 and took about 5 minutes, MiniMax M3.1 Flash $0.029 and about 3 minutes.
Who made FawnBench?
@fawnunwrap introduced it on X on October 19, 2026 (“This is my benchmark… its js making a deer”). Every post on this page is from that account. Other accounts’ FawnBench clips we found were re-uploads of these videos, so they are not included.
Results by model
Only numbers stated in each post. “—” means the post doesn’t say.
Summary
4 posts on X run this test with MiniMax M3.1 Flash, Claude Haiku 5.5, DeepSeek V4.1 Flash 1017, GPT-6.1 Terra, Gemini 4 Argon, GPT-6 Astra, Claude Opus 5.5 and GPT-6.1 Sol. @fawnunwrap, @fawnunwrap, @fawnunwrap report per-model numbers (see the table).
Who won where
1- FawnBench round 1: the deerDeepSeek “didn’t do bad for the price”; no winner was named.— the author’s view, @fawnunwrap (paraphrased)