GPT-6 Luna vs MiniMax M3.1 Flash
aka Luna vs M3.1-Flash
- CheaperGPT-6 Luna2/2 postsmedian gap ~4.4×
- FasterGPT-6 Luna2/2 postsmedian gap ~24×
As stated in each post, not a controlled benchmark.
Posts
4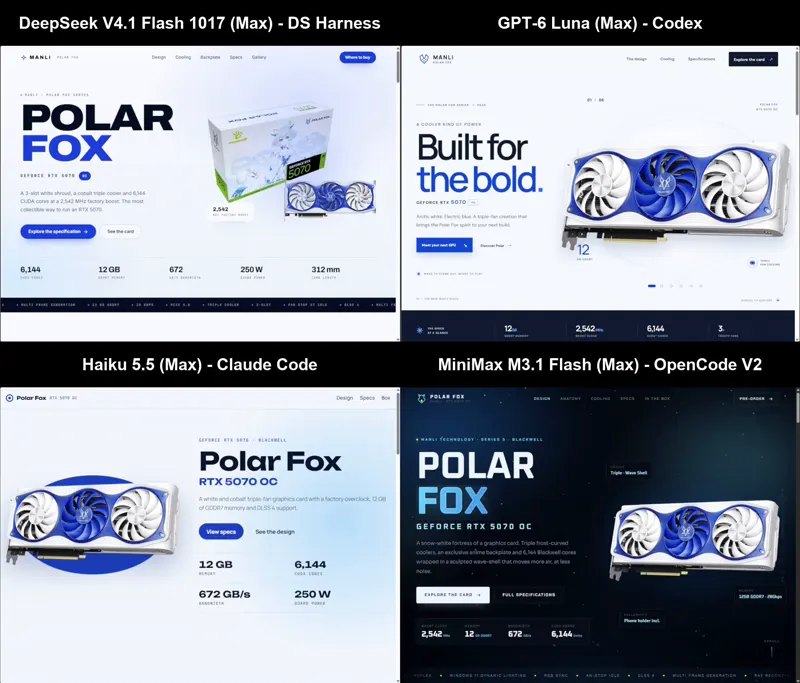

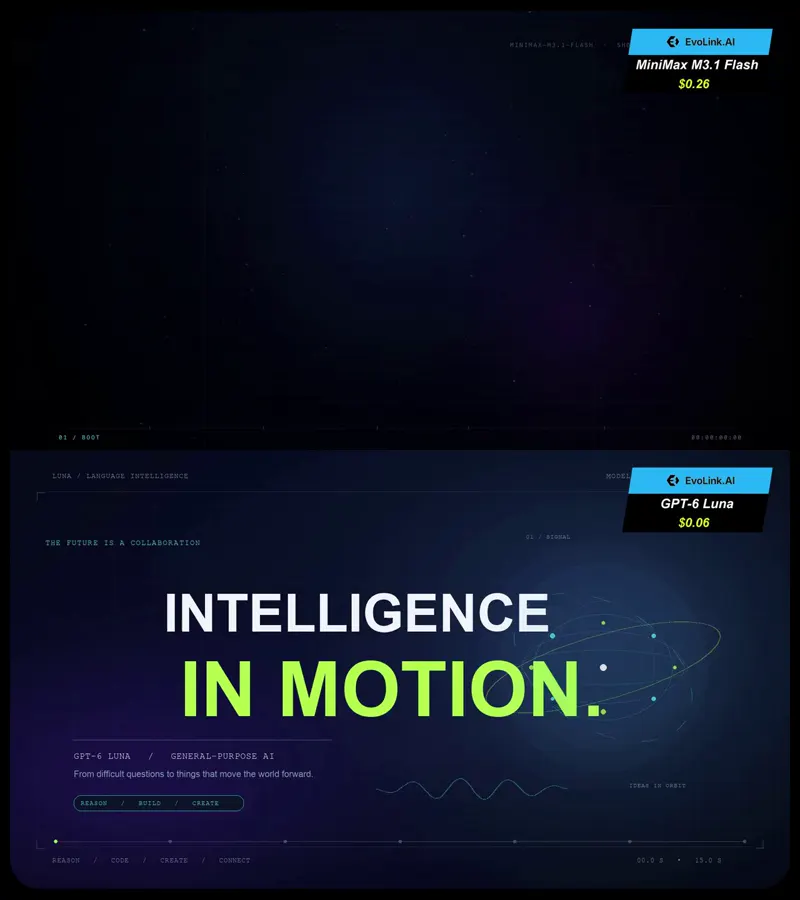

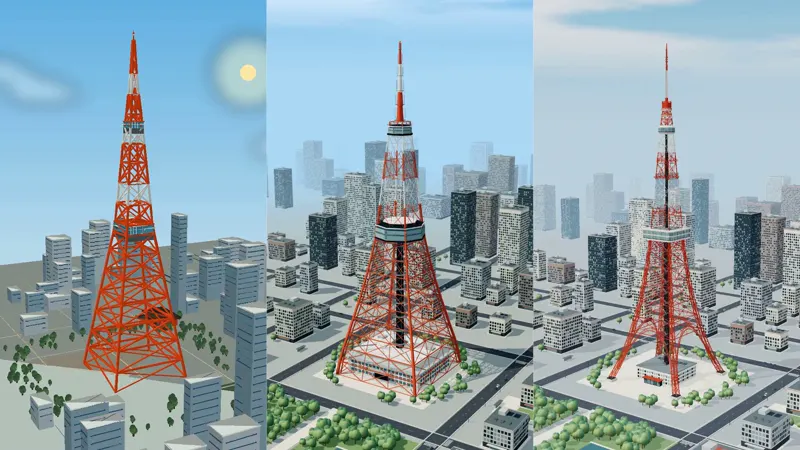
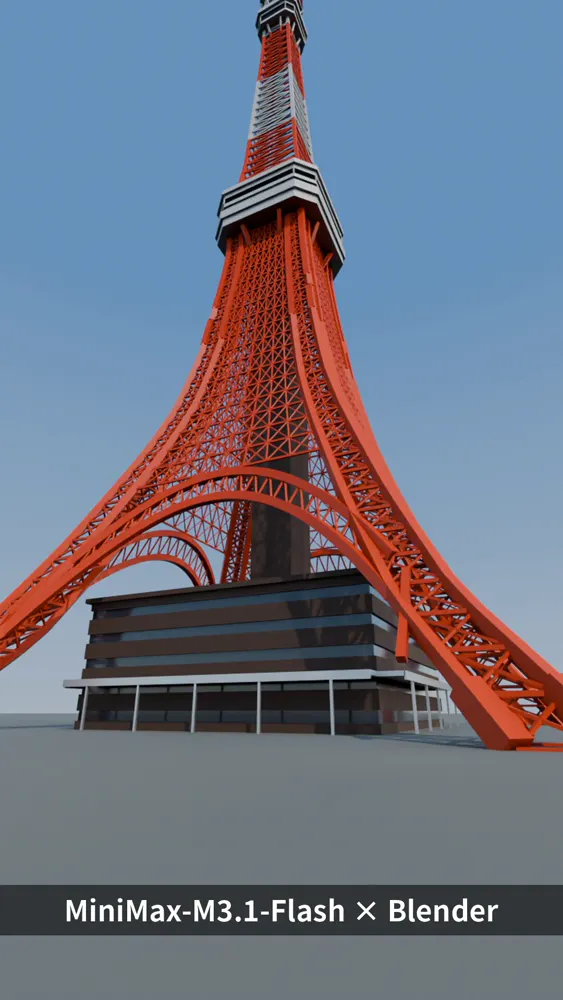
Motion-graphics showreel, GPT-6 Luna vs MiniMax M3.1 Flash: GPT-6 Luna, MiniMax M3.1 Flash. Posted by @EvoLinkAi.
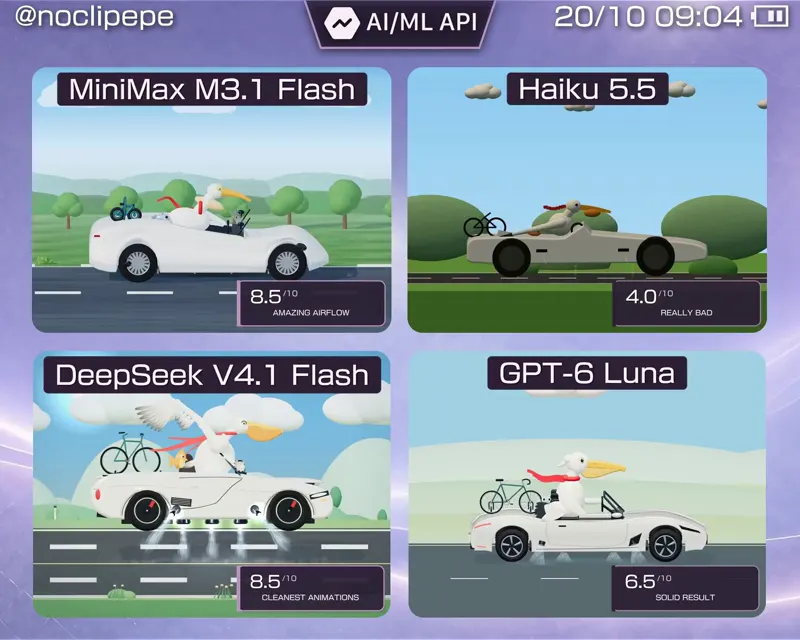

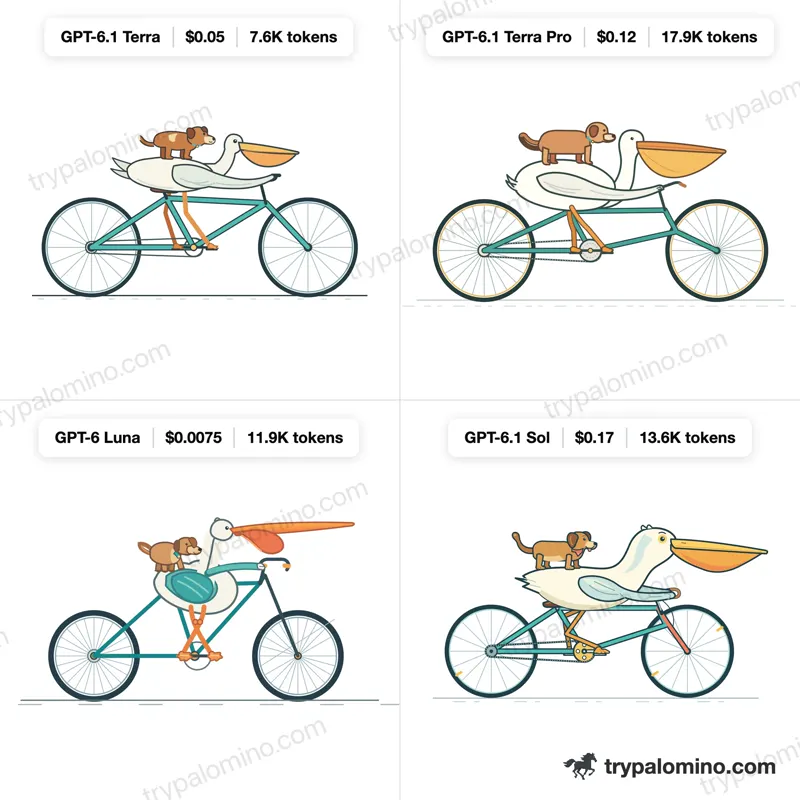
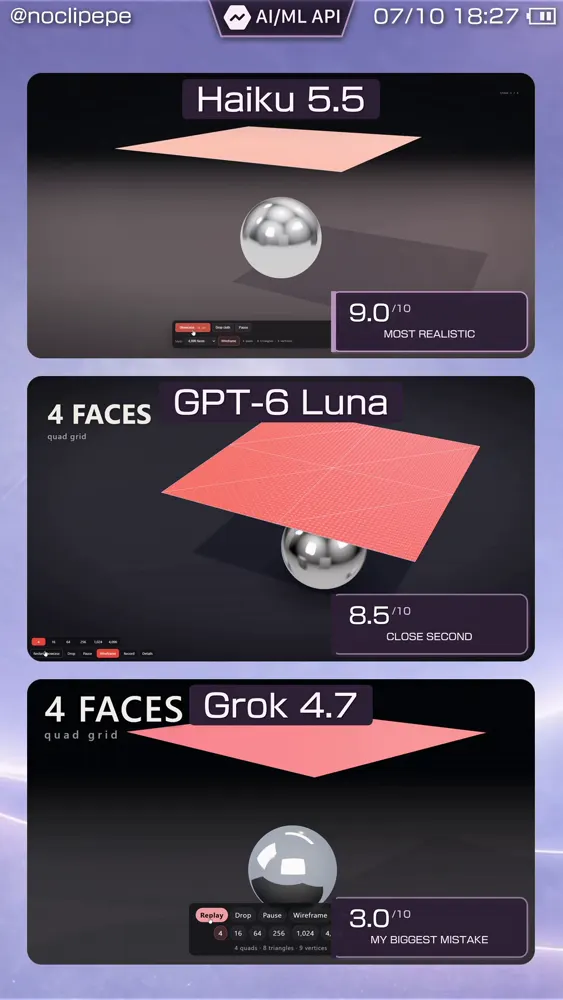
Pelican driving a flying roadster: MiniMax M3.1 Flash, Claude Haiku 5.5, DeepSeek V4.1 Flash 1017, GPT-6 Luna. Posted by @noclipepe.
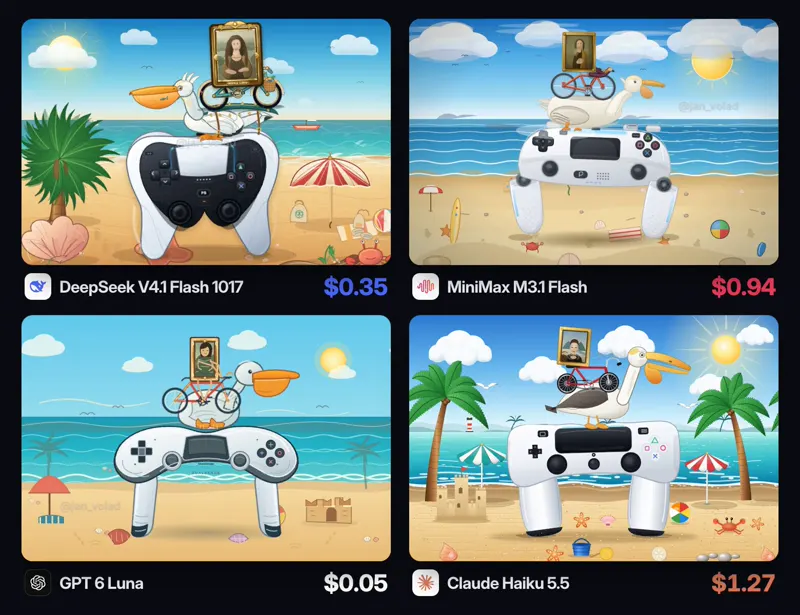

Mona Lisa on a pelican on a PS5 controller: DeepSeek V4.1 Flash 1017, MiniMax M3.1 Flash, GPT-6 Luna, Claude Haiku 5.5. Posted by @jan_volad.
Same prompt, separate runs
5Not a controlled comparison: prompts, tools and time differ.







About this matchup
GPT-6 Luna vs MiniMax M3.1 Flash in real side-by-side tests: 4 posts from X where both got the same prompt; 3 posts report cost or time. Judge coding ability from the actual outputs.
GPT-6 Luna vs MiniMax M3.1 Flash: which is better for coding?
Which is better for coding, GPT-6 Luna or MiniMax M3.1 Flash?
None of the 4 posts here names one of the two as the better result, so judge the outputs above for the work you care about.
Which is cheaper, GPT-6 Luna or MiniMax M3.1 Flash?
2 posts state a cost for both: GPT-6 Luna was cheaper in both (median gap ~4.4×). These are the costs the posts state for each run, not list prices.
Which is faster, GPT-6 Luna or MiniMax M3.1 Flash?
2 posts state a time for both: GPT-6 Luna was faster in both (median gap ~24×). Times are as stated in each post; tools and settings differ between posts.
Summary
GPT-6 Luna and MiniMax M3.1 Flash appear together in 4 posts on X: GPU showcase website from given image assets, four models (@VulKan42069), motion-graphics showreel, GPT-6 Luna vs MiniMax M3.1 Flash (@EvoLinkAi), pelican driving a flying roadster (@noclipepe) and mona Lisa on a pelican on a PS5 controller (@jan_volad). 3 of them are part of larger lineups with other models. In @noclipepe's pelican driving a flying roadster, GPT-6 Luna was cheaper ($0.14 vs $0.62) and faster (17.7 min vs 43.9 min), as reported in the post. In @VulKan42069's GPU showcase website from given image assets, four models, GPT-6 Luna was faster (3.3 min vs 2 h 28 min), as reported in the post. In @EvoLinkAi's motion-graphics showreel, GPT-6 Luna vs MiniMax M3.1 Flash, GPT-6 Luna was cheaper ($0.06 vs $0.26), as reported in the post.
What each post reports
| Post | Model | Time | Cost | Tokens | Author’s verdict | Post |
|---|---|---|---|---|---|---|
| GPU showcase website from given image assets, four models@VulKan42069 | GPT-6 Luna | 3.3 min | — | — | — | X post |
| GPU showcase website from given image assets, four models@VulKan42069 | MiniMax M3.1 Flash | 2 h 28 min | — | — | — | X post |
| Motion-graphics showreel, GPT-6 Luna vs MiniMax M3.1 Flash@EvoLinkAi | GPT-6 Luna | — | $0.06 | — | GPT-6 Luna gives its showreel more breathing room than MiniMax M3.1 Flash. | X post |
| Motion-graphics showreel, GPT-6 Luna vs MiniMax M3.1 Flash@EvoLinkAi | MiniMax M3.1 Flash | — | $0.26 | — | GPT-6 Luna gives its showreel more breathing room than MiniMax M3.1 Flash. | X post |
| Pelican driving a flying roadster@noclipepe | MiniMax M3.1 Flash | 43.9 min | $0.62 | — | — | X post |
| Pelican driving a flying roadster@noclipepe | GPT-6 Luna | 17.7 min | $0.14 | — | — | X post |
| Mona Lisa on a pelican on a PS5 controller@jan_volad | MiniMax M3.1 Flash | — | — | — | — | X post |
| Mona Lisa on a pelican on a PS5 controller@jan_volad | GPT-6 Luna | — | — | — | — | X post |
Only numbers stated in each post. “—” means the post doesn’t say.
Quick facts
| Model | Vendor | Released | Input $/1M tokens | Output $/1M tokens | Context (tokens) | Official links |
|---|---|---|---|---|---|---|
| GPT-6 Luna | OpenAI | |||||
| MiniMax M3.1 Flash | MiniMax | 2026-09-27 | 1,000,000 | Model docs |
From the vendors’ official pages, checked 2026-10-19. Standard API list prices; each value links its source and a blank cell could not be verified. The archive’s own numbers above are what each post states.
Who won where
1- Motion-graphics showreel, GPT-6 Luna vs MiniMax M3.1 FlashGPT-6 Luna gives its showreel more breathing room than MiniMax M3.1 Flash.— the author’s view, @EvoLinkAi (paraphrased)
Models
Related matchups
DeepSeek V4.1 Flash 1017 vs MiniMax M3.1 Flash91 posts · 115.3K viewsClaude Opus 5.5 vs MiniMax M3.1 Flash37 posts · 20.6K viewsGemini 4 Argon vs MiniMax M3.1 Flash10 posts · 3.2K viewsClaude Haiku 5.5 vs MiniMax M3.1 Flash9 posts · 6.3K viewsGPT-6.1 Sol vs MiniMax M3.1 Flash8 posts · 19.9K viewsGPT-6 Astra vs MiniMax M3.1 Flash8 posts · 15.3K views