Mechanical watch (3D)
aka watchmaker benchmark
An interactive 3D mechanical skeleton watch with an exploded view in Three.js.
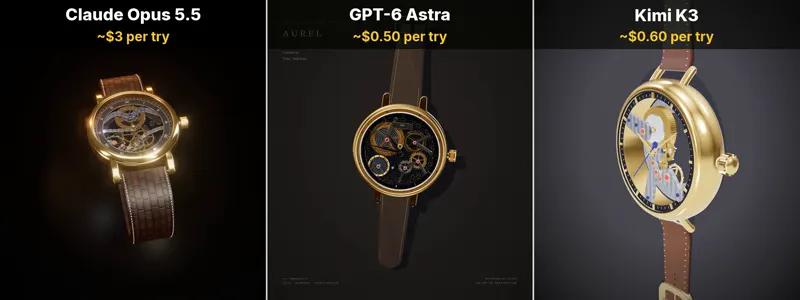
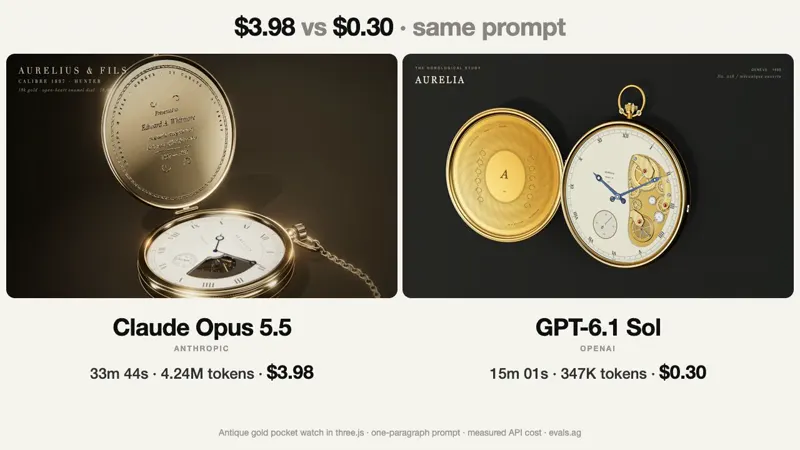
- Claude Opus 5.5Picked by 2 posters$3.00–$3.98 · 23.7 min
- DeepSeek V4.1 Flash 1017@YxzRainy’s pick
- GPT-6.1 Sol$0.30–$1.40 · 15 min–15.4 min
- Claude Sonnet 5.5$13.47 · 38.6 min
- GPT-6 Astra$0.50
- Kimi K3$0.60
- Kimi K3.1 Pro50 min
Not a controlled comparison: prompts, tools and time differ.
By model
5 posts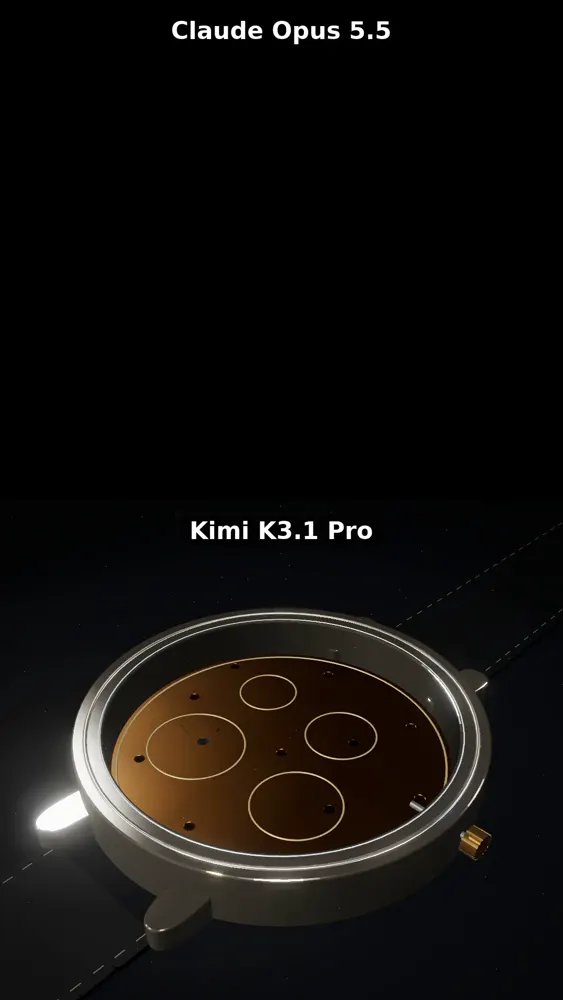



GPT-6.1 Sol3
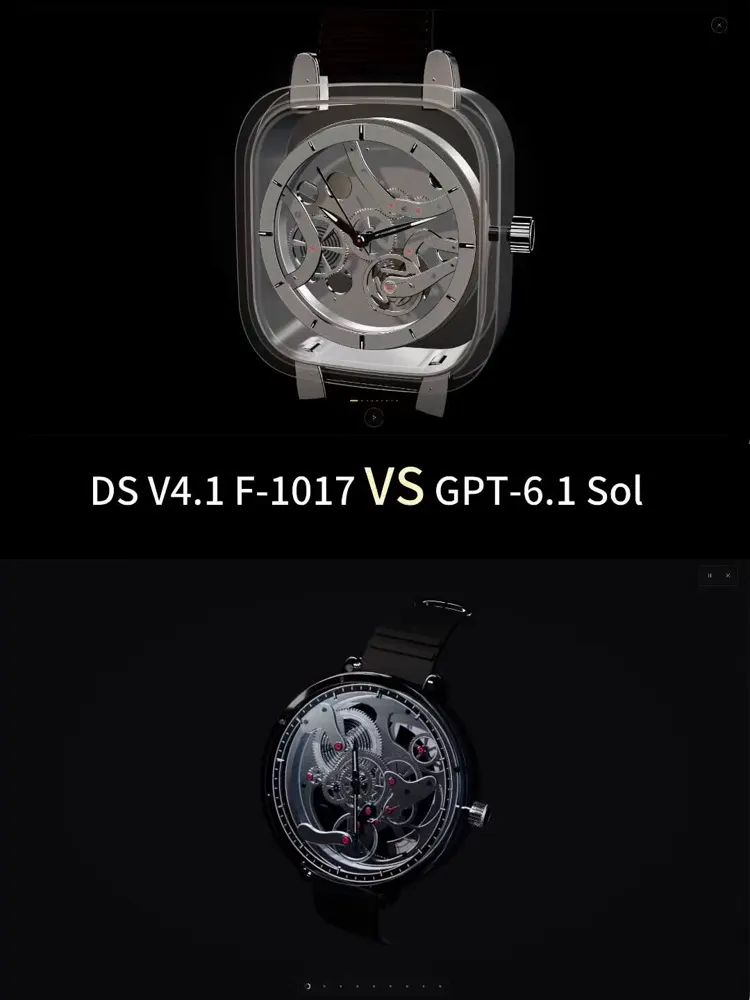

Mechanical skeleton watch, DeepSeek vs GPT-6.1 Sol: DeepSeek V4.1 Flash 1017, GPT-6.1 Sol. Posted by @YxzRainy.
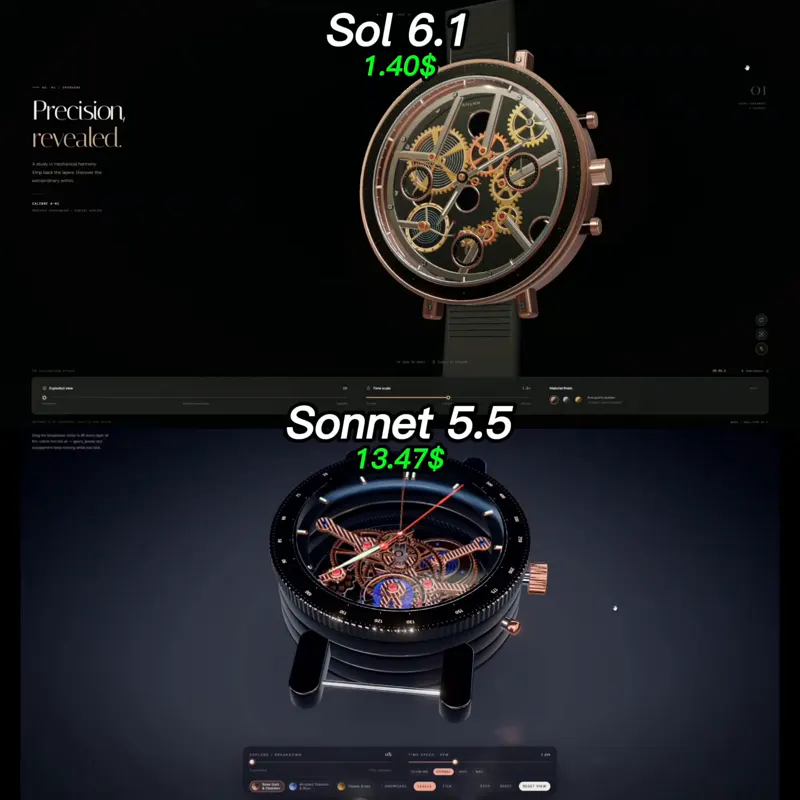

Mechanical skeleton watch, exploded: Claude Sonnet 5.5, GPT-6.1 Sol. Posted by @olezhavich.
3D pocket watch, Claude Opus 5.5 vs GPT-6.1 Sol: Claude Opus 5.5, GPT-6.1 Sol. Posted by @maker_evan.
About this test
The mechanical watch (3D) test, run by 7 models across 5 posts on X. Watch each result, then compare what the posts report below.
Posts ask a model to build a mechanical watch in code, usually Three.js: a skeleton or pocket watch with turning gears, often with an exploded view that pulls the movement apart. Wording differs between posts, so results are only loosely comparable.
No fixed wording; posts use variations on the same idea.
Other wordings
A full Swiss lever movement in Three.js: real gear ratios, a working escapement, a breathing hairspring, and hands that tell the actual time.
Mechanical watch AI test: questions and answers
Which AI builds the best mechanical watch in Three.js?
There is no overall winner: 3 of the 5 posts here name one, each a different model. In @YxzRainy’s skeleton watch the author preferred DeepSeek V4.1 Flash 1017 to GPT-6.1 Sol; in @HavisT83099’s luxury skeleton watch the author picked Claude Opus 5.5 over GPT-6 Astra and Kimi K3; in @kairox36’s watch assembly the author picked Claude Opus 5.5 over Kimi K3.1 Pro. @olezhavich (Claude Sonnet 5.5 vs GPT-6.1 Sol) and @maker_evan (Claude Opus 5.5 vs GPT-6.1 Sol) did not name a winner. Each post uses its own prompt and setup.
Claude or GPT-6.1 Sol for a 3D mechanical watch?
Neither author who ran Claude against GPT-6.1 Sol picked one. @olezhavich says Sol went for a luxury product showcase with smooth case separation and clean typography, while Claude Sonnet 5.5 built a fully labeled movement with every gear floating on the central axis, and asks readers which approach they like more. @maker_evan’s Claude Opus 5.5 vs Sol post has no verdict in its text.
How much does an AI mechanical watch build cost?
As the authors state them: about $13.47 for Claude Sonnet 5.5 and $1.40 for GPT-6.1 Sol in @olezhavich’s run (estimated API prices), about ¥3 for DeepSeek V4.1 Flash 1017 in @YxzRainy’s (¥2.7, per a reply), and per try about $3 for Claude Opus 5.5, $0.50 for GPT-6 Astra and $0.60 for Kimi K3 in @HavisT83099’s. The results table below lists every figure each post reports.
What is the watchmaker benchmark?
A name @huy0x used in June 2026 for asking a model to build a full Swiss lever watch movement in Three.js, with real gear ratios, a working escapement and a hairspring; the first run was Claude Fable 5. Later posts build skeleton, pocket and exploded-view watches; the ones on aivs.tv are listed on this page.
Results by model
Only numbers stated in each post. “—” means the post doesn’t say.
Summary
5 posts on X run this test with Claude Opus 5.5, Kimi K3.1 Pro, GPT-6 Astra, Kimi K3, DeepSeek V4.1 Flash 1017, GPT-6.1 Sol and Claude Sonnet 5.5. @kairox36, @HavisT83099, @maker_evan, @olezhavich report per-model numbers (see the table).
Who won where
3- Mechanical watch assembly in 3DThe poster says Kimi K3.1 Pro had all the time in the world and still lost to Claude Opus 5.5.— the author’s view, @kairox36 (paraphrased)
- Luxury skeleton watch, Opus vs Astra vs Kimi K3Opus has the real-looking strap and shining gold; Astra’s strap is rough and its gold flat; Kimi’s strap is cartoonish.— the author’s view, @HavisT83099 (paraphrased)
- Mechanical skeleton watch, DeepSeek vs GPT-6.1 SolDeepSeek nails the matte metal, gear detail, mechanism and lighting; GPT is decent but its metal looks worse and many gears do not turn.— the author’s view, @YxzRainy (paraphrased)